QueryFlux documentation
QueryFlux is a high-performance, protocol-aware SQL proxy for analytical and operational engines. Clients connect with the drivers they already use (Trino HTTP, PostgreSQL wire, MySQL wire, Snowflake HTTP wire and SQL API v2, Arrow Flight). QueryFlux routes each query to the right backend, translates SQL dialects when needed, and exposes a single observability surface — so you stop wiring N clients × M engines by hand.
One endpoint. Multiple engines. Native protocols.
The ideas mirror what proxies like ProxySQL do for MySQL/PostgreSQL fleets: place a smart tier in front of your databases, centralize routing and limits, and keep clients simple. QueryFlux applies that pattern to multi-engine analytics (Trino, DuckDB, StarRocks, Athena, and more) and lakehouse workloads.
Quick guides
config.yaml — frontends, cluster groups, routers, persistence, admin API.What is QueryFlux?
Modern stacks mix many query engines — each with its own wire protocol and SQL dialect. QueryFlux sits between clients and engines: it accepts familiar protocols, matches routing rules (protocol, headers, SQL patterns, tags, or scripted logic), then dispatches to a cluster group with concurrency limits and optional sqlglot dialect translation.
Typical outcomes:
- Cost-aware routing — steer CPU-heavy work to compute-priced clusters and selective scans to pay-per-scan engines.
- SLA protection — cap concurrent queries per group; queue at the proxy instead of overloading backends.
- Transparent migration — split traffic by weight between engines without client changes.
For a deeper product rationale, see Motivation and goals and Benchmarks. On the QueryFlux blog: Why QueryFlux, Iceberg on Trino and StarRocks, Offload Snowflake queries, and Row filters above the engines. For the broader control-plane argument, see The Future Isn't One Engine on the LakeOps blog.
How does it work?
Every query passes through three stages:
1. Protocol ingestion
QueryFlux listens on multiple frontends at once:
| Frontend | Default port | Typical clients |
|---|---|---|
| Trino HTTP | 8080 | Trino CLI, JDBC, Python |
| PostgreSQL wire | 5432 | psql, Postgres drivers |
| MySQL wire | 3306 | mysql, JDBC, BI tools |
| Snowflake HTTP + SQL API v2 | configurable (e.g. 8443) | Snowflake JDBC/ODBC/Python, SnowSQL, REST v2 |
| Arrow Flight SQL | gRPC | Flight-native clients |
Details: Frontends and Snowflake frontend.
2. Routing
Rules are evaluated in order. The first match selects a cluster group. You can match on protocol, HTTP headers, SQL text (regex), Trino client tags, compound logic, or Python for custom routing. A fallback group catches everything else.
Details: Routing and clusters. For multi-warehouse expansion (Snowflake/Databricks variants), health checks, and running-query reconciliation, see Cluster variants, health checks & reconciliation.
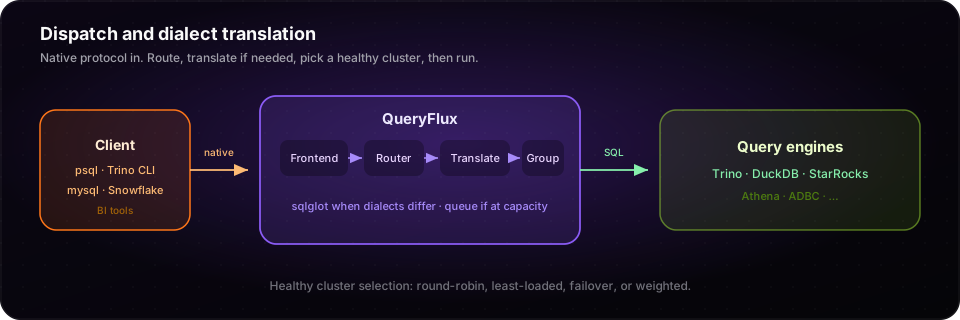
3. Dispatch and dialect translation
QueryFlux picks a healthy cluster (round-robin, least-loaded, failover, weighted), optionally rewrites SQL for the target dialect, and runs the query. If the group is at capacity, queries queue at the proxy.
Reference manual
Use these when you already know what you are looking for:
| Topic | Doc |
|---|---|
| YAML reference | Configuration |
| System layout | Architecture overview, System map |
| Dialect rewriting | Query translation |
| Tags and routing | Query tags |
| Metrics and health | Observability |
| Wire protocols | Frontends |
| Extending engines | Adding engine support |
| Auth setup | Authentication & identity |
| Access control | Overview, OPA, Customer API row filters |
| Auth internals | Auth & authorization design |
Project resources
| Page | Purpose |
|---|---|
| Development | Build from source, venv, make env, tests |
| Contribute | PRs, issues, community |
| Project structure | Repository layout |
| Roadmap | Shipped vs planned features |
| QueryFlux blog | Why QueryFlux, agents, row filters / column masks, Iceberg routing, Snowflake offload |
| The Future Isn't One Engine | Why routing belongs in a control plane, not inside a warehouse |